Evaluating Enterprise Platforms for Indirect Prompt Injection Detection
Most enterprises deploy AI agents without defenses regulators will soon require.
Evaluating Enterprise Platforms for Indirect Prompt Injection Detection.
Why indirect prompt injection is now an enterprise security problem, not a research curiosity
Nobody types the attack in. The agent just encounters it while doing its job. That distinction matters because it changes who has to defend against it, and how.
The root of the problem sits deep in how language models work. An LLM doesn't separate the instructions it's supposed to follow from the data it's supposed to process, because both arrive as the same stream of tokens. There's no built-in trust boundary between "here's your job" and "here's some text you're reading." OWASP recognized how serious this is by ranking prompt injection, LLM01, as the number one risk in its 2025 LLM Top 10, and it held that position into the 2026 update Cloud Security Alliance.
Telemetry backs up what used to be theoretical. Google found a 32% relative increase in malicious IPI content across roughly 2 to 3 billion crawled pages between November 2025 and February 2026. In systems that let agents act on what they read, an empirical study cited by Vectra puts the attack success rate at 84% Vectra AI. Those aren't lab numbers from a controlled red-team exercise. They describe live conditions.
The incident list from the past year makes the shift concrete. EchoLeak, tracked as CVE-2025-32711, pulled data out of Microsoft 365 Copilot through a single email the victim never even opened. GrafanaGhost, disclosed on April 7, 2026, was mapped by OWASP's GenAI Q1 2026 Exploit Round-up as LLM01 + LLM02 + LLM05 + ASI01 + ASI02 + ASI09. Bloomberg reported that Claude had been used to steal data from the Mexican government. ServiceNow's Now Assist had its own flaw, nicknamed BodySnatcher and tracked as CVE-2025-12420, patched back in October 2025 Cloud Security Alliance.
OpenAI acknowledged on February 13, 2026 that prompt injection in AI browsers "may never be fully patched". That's a direct statement. That's an admission that the vulnerability is structural rather than a bug waiting for a fix. It's structural. And if it's structural, evaluating a platform on whether it patches known exploits misses the point entirely. What matters is whether the platform catches new ones, continuously, as they appear in the system. Representative 2025–2026 incidents ground the operational claim that indirect prompt injection is now an enterprise security problem, not a research curiosity.
Why the agentic deployment model raises the stakes beyond standard LLM risk
A chatbot that gets tricked into saying something embarrassing is a reputational problem. An agent that gets tricked into sending money is a different category of event entirely. Once an agent has real tool access, sending email, executing terminal commands, calling payment APIs, committing code, prompt injection becomes a lever for unauthorized action rather than a text-generation flaw.
Cisco's State of AI Security 2026 report found that 83% of organizations plan to deploy agentic AI, but only 29% feel ready to do it securely. Enterprises are racing ahead of their own defenses.
Stored injection is the variant that should worry security teams the most. Instead of a payload arriving at the moment of use, it sits pre-planted in long-term memory, a RAG knowledge base, an embedding, or an agent's config file, waiting. The exploitation event and the injection event can be separated by weeks. A scanner that only inspects the prompt at inference time never sees the planting. It only sees the trigger, if it sees anything at all.
Researchers have started framing IPI less like a single exploit and more like a full intrusion. A paper on what's being called the "promptware kill chain" breaks it into stages: initial access, privilege escalation, reconnaissance, persistence, command and control, lateral movement, and finally action on objective. Why does that framing matter? Because each stage calls for a different kind of detection. Catching the initial access doesn't help if persistence has already been established somewhere else in the pipeline.
A researcher at Forcepoint described the risk gradient: an AI browser that only summarizes web pages is low-stakes, but an agent wired into email, a terminal, or a payment system is a genuine target, and that's exactly the profile most enterprises were actively deploying through the first half of 2026. Forcepoint's X-Labs documented the intent behind real payloads in April 2026, and it wasn't academic: forced PayPal transfers, Stripe donation redirection fraud, recursive file deletion inside IDE agents, API key theft. None of that is hypothetical anymore. The surface keeps widening too. Instructions hidden inside images that accompany otherwise ordinary text extend the attack beyond anything a text-only pipeline was built to catch.
The regulatory and governance context shaping what "adequate" detection means
Adequate according to whom? Prompt injection risk doesn't sit inside one tidy framework. It maps across OWASP, MITRE ATLAS, NIST, the EU AI Act, ISO 42001, GDPR, and NIS2 simultaneously. A platform has to hold up under all of those lenses at once, not just the one a vendor's marketing page leans on.
The EU AI Act gives the clearest teeth so far. Article 15 requires high-risk AI systems to maintain accuracy, robustness, and cybersecurity across their entire lifecycle, and that cybersecurity standard covers resilience against adversarial examples and model evasion, a category prompt injection fits into even though the text doesn't name it directly. Articles 72 and 73 go further: Article 72 requires a documented monitoring system starting on day one of deployment, and Article 73 sets incident reporting deadlines (2 days for widespread infringements or serious incidents causing fundamental-rights harm, 10 days when a death may have occurred, and 15 days for all other serious incidents). Following the May 2026 Digital Omnibus finalization, compliance for standalone high-risk systems under Annex III, things like recruiting tools and credit scoring, got pushed to December 2, 2027. But monitoring obligations start at deployment, not at that deadline. Organizations don't get a grace period on watching what their systems are doing.
NIST is heading somewhere similar. Its Control Overlays for Securing AI Systems, or COSAIS, has a public draft expected in fiscal year 2026, and the agency's NIST/CAISI technical blog from January 2025, "Strengthening AI Agent Hijacking Evaluations," signals where mandatory controls are likely headed Cloud Security Alliance. The trouble is that governance hasn't caught up with deployment. Only 18% of organizations report having fully implemented AI governance frameworks, even though most of them are already running AI in production Vectra AI. That's a wide gap. That's most of the market operating without the guardrails regulators are about to require.
Red-teaming is turning into something closer to compliance evidence than best practice. Organizations will likely need to show adversarial testing against prompt injection and jailbreak attempts, fuzzing of RAG pipelines, and regression-tested mitigations to satisfy how EU AI Act audits are expected to work. Five Eyes, the joint intelligence alliance of CISA, NSA, the UK, Canada, Australia, and New Zealand, put out guidance in May 2026 naming prompt injection as a core manipulation vector and stating that strong governance, monitoring, and human oversight are "essential prerequisites," not optional.
Put together, these facts write the evaluation criteria themselves. A platform that fires off detection alerts with no audit trail, no timestamps, no mapping back to a named framework, isn't going to satisfy Article 72 or 73, and it won't hold up as red-team evidence either. Detection accuracy matters. The paperwork behind it creates the same problem.
What the three-layer defense model means for how platforms should be structured
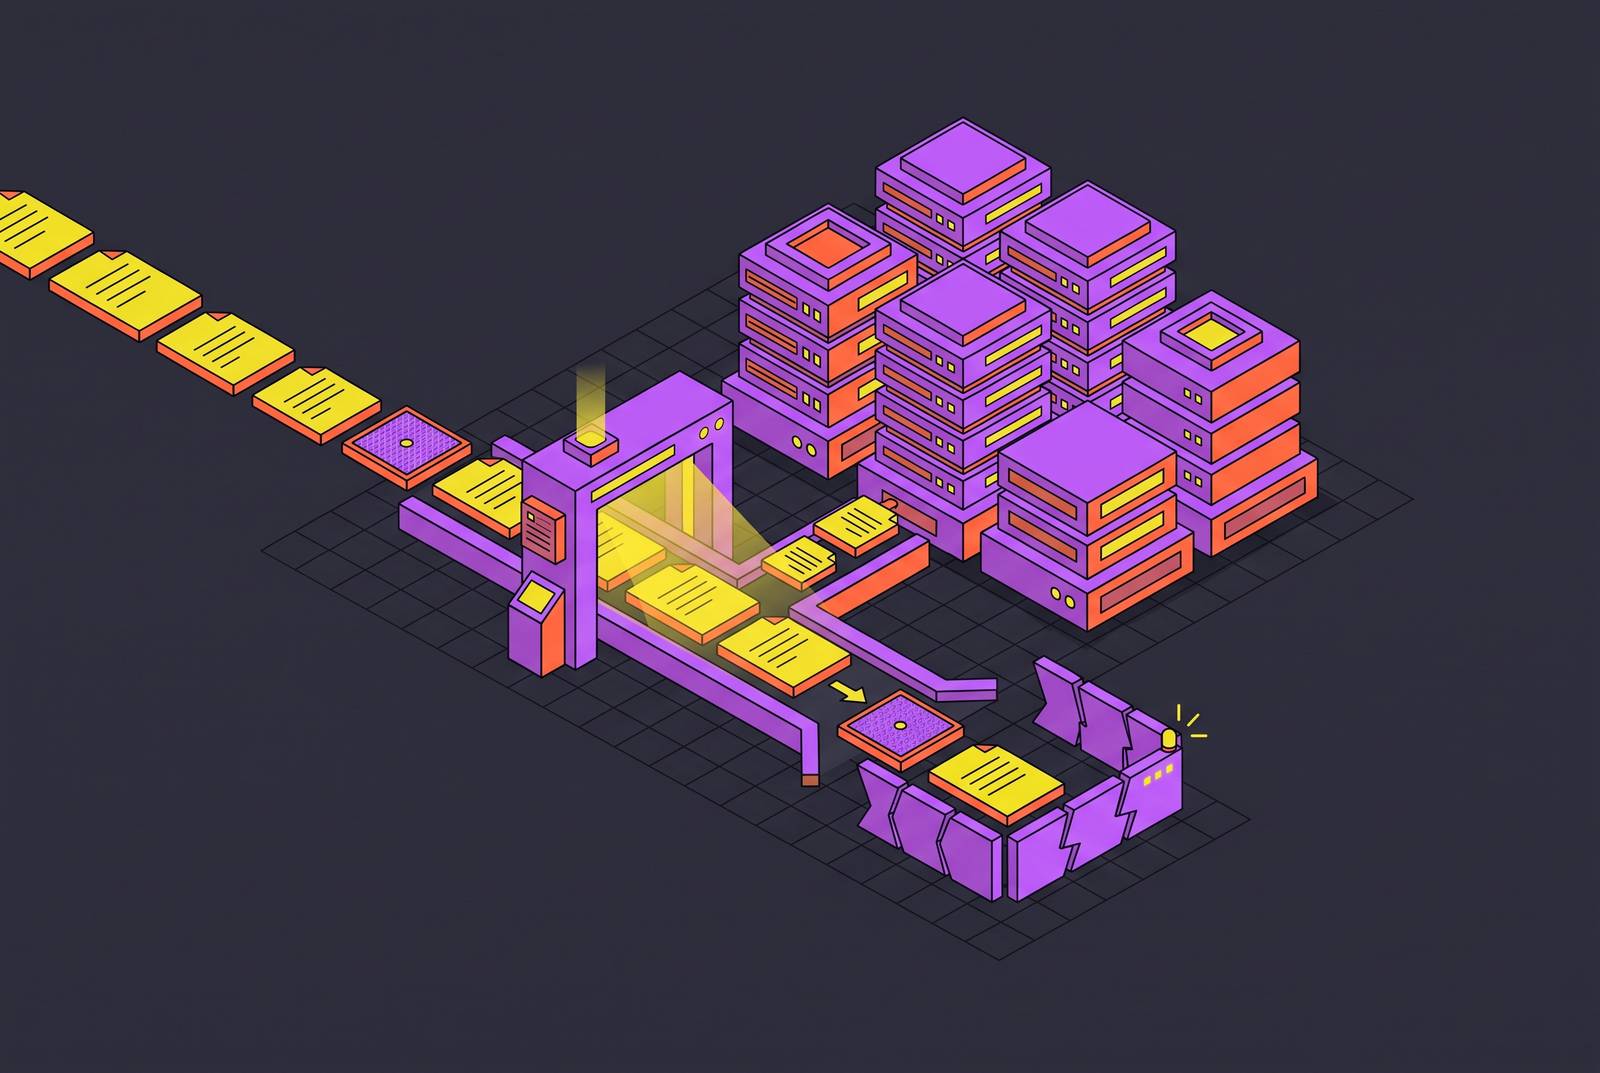
Security researchers converge on a pattern. Sysdig's 2026 analysis, the Five Eyes guidance, and OWASP all land on the same conclusion from different directions: no single control solves IPI. A real defense needs three layers working in concert, not one clever filter bolted onto the front of the pipeline.
Why doesn't one layer suffice? Adaptive attacks bypass essentially every published single-point defense, according to Sysdig's analysis. Think about the economics involved. An attacker only needs one payload to slip through once. A defender has to block every malicious instruction across every input the agent touches, emails, documents, web pages, internal wikis, even the outputs of other agents. That asymmetry alone should tell you why layering isn't optional.
Layer one is architectural prevention: separating system instructions from retrieved content at the structural level, minimizing what privileges an agent actually needs, tagging incoming content by trust level before it ever reaches the context window. Five Eyes guidance adds a human-in-the-loop checkpoint at consequential decisions, the kind of manual gate that catches what automated layers miss.
Layer two is runtime detection. This includes straightforward pattern matching against known triggers like "ignore previous instructions," necessary but nowhere near sufficient on its own, plus semantic analysis built to catch obfuscated payloads hidden in CSS-suppressed text, zero-pixel fonts, HTML comments, a common text-encoding scheme, or Unicode tag characters. Speed matters here more than most buyers expect. Inline scanning has to run fast enough that it doesn't choke the agent's workflow, and sub-50ms has become the benchmark dedicated products are measured against.
Layer three is continuous monitoring, watching what an agent ingests after deployment rather than only scrutinizing what a user submits. That means scanning long-term memory and RAG indexes for payloads that were planted earlier and are just waiting, and it means covering third-party plugins, connectors, and model APIs, since vendor AI assets open injection surfaces that internal controls simply don't reach. It also means logging incidents with timestamps and framework mappings so the record actually supports an audit later.
That third layer runs into a disclosure problem. Of eight major AI incidents tracked in Q1 2026, only one received a CVE. Bug bounties that Anthropic, GitHub, and Google paid out for specific IPI flaws in the GitHub Actions integrations of Claude Code, Copilot Agent, and Gemini CLI never generated CVEs or public advisories, even though other prompt injection flaws in those same tools did. So a platform leaning on CVE feeds as its main threat intelligence source is structurally blind to most of what's actually happening in the wild.
Criterion 1: How well a platform handles the architectural prevention layer
Start with a basic question: does the platform actually enforce prompt boundary separation, or does it just assume the application developer already handled that? A lot of tooling in this space quietly punts that responsibility upstream.
Privilege minimization is the next thing to check. Does the platform give teams a way to define and enforce least-privilege agent permissions, and can it flag when an agent calls a tool outside its declared scope? That kind of out-of-bounds tool call is often the clearest signal that an injection succeeded, even when nobody caught the payload itself.
Input provenance matters just as much. Can the platform tag content by where it came from, an internal trusted system versus the open web versus a user-uploaded file, and apply different scrutiny depending on the source? And does that coverage extend past plain text into images and structured data files, given how much of the injection surface has moved into multimodal inputs?
RAG pipeline hardening deserves its own line of questioning. Does the platform scan RAG indexes and knowledge bases for payloads that are already stored there, rather than only checking the prompt at the moment of inference? A model can be perfectly well-behaved at inference time and still pull a poisoned chunk out of its own knowledge base.
Self-hosting doesn't solve this either. Researchers demonstrated successful injection against local models including Mozilla's Tabstack and Cotypist, so air-gapping isn't a shortcut around detection. Regulated industries may still need air-gapped deployment for other reasons, but buyers in that position should confirm the platform keeps its detection capability intact rather than stripping it out for the on-prem version.
Ask any vendor a few direct questions. Where does the product actually sit: the application layer, the API gateway, the model itself, or the agent orchestrator? Does using it mean rewriting how the application builds its prompts, or does it work without touching that code?
Criterion 2: Runtime detection capabilities and their measurable limits
Sysdig, Five Eyes, and OWASP all converge on the point that no single control solves IPI, and that a real defense requires three layers working together. Signature matching is fast and produces few false positives against known payloads, but it's blind to anything novel. Semantic classifiers, trained on adversarial examples, generalize better but cost latency and need regular retraining to stay useful. Behavioral anomaly detection skips the prompt entirely and watches what the agent actually does downstream, which catches injections that slipped past the input layer but still managed to change behavior.
As of September 2026, no independent third-party benchmark comparing detection rates across major platforms had been published by a recognized testing body. That leaves buyers largely dependent on vendor-reported numbers, which should be read as directional rather than verified. A detection rate measured against a static benchmark says very little about performance against an attacker actively tuning payloads to slip past that specific product.
What's a fairer baseline? The MDPI meta-analysis cited by Vectra puts attack success rates at 66.9%–84.1% in agent systems with auto-execution Vectra AI (meta-analysis reference). That range is the bar a runtime detector actually needs to clear in production, not whatever score it posted on a clean internal test set.
Latency isn't a footnote here, it's a real evaluation axis. Inline detection that runs synchronously has to stay fast enough that it doesn't wreck the usability of an agentic workflow, and sub-50ms has become the line dedicated API-first products are held to. Ask for p95 and p99 figures under realistic load. A mean latency number on a quiet test environment tells you almost nothing about how the tool behaves during a traffic spike.
Obfuscation resistance separates the serious products from the rest. Unit 42 documented 22 distinct payload-delivery techniques active in the wild as of April 2026. A runtime detector worth paying for needs to handle CSS-suppressed text, zero-pixel fonts, HTML comment injection, Base64-staged payloads, and Unicode tag characters, all of it. Ask directly whether a vendor has been tested against Forcepoint's documented payload corpus or something equivalent.
Language coverage is easy to overlook and shouldn't be. Lakera Guard claims detection accuracy above 98% across more than 100 languages, drawing on data from the Gandalf adversarial challenge. Headline figures like that should be checked against the specific languages an organization actually operates in, since aggregate numbers can mask real gaps in less common ones. And it's fair to ask any vendor outright whether they can demonstrate detection against Base64-staged or Unicode-obfuscated payloads specifically, since that's often where the gap between marketing and reality first becomes visible.
Criterion 3: Continuous monitoring for vendor AI assets and post-deployment threats
Detection at the moment of inference only covers part of the exposure. An organization doesn't directly control everything else: third-party plugins, connectors, and model APIs that get bolted onto an agentic stack after the fact. Each one is a door that internal architectural controls simply weren't built to watch.
Stored injection monitoring belongs here too, not just under prevention. Scanning long-term memory, RAG indexes, and knowledge bases isn't a one-time setup task, it has to run continuously, because payloads can sit dormant for weeks before something triggers them. A platform that only checks these stores at onboarding time will miss whatever gets planted afterward.
Given the CVE disclosure gap already described, vendor asset monitoring can't lean on public vulnerability feeds as its early-warning system. Teams need visibility into what their connectors are actually doing, not a wait for someone else to publish an advisory.
None of it counts for much without the paperwork to back it up. Incident logs need timestamps and mappings to the relevant framework, because that's what turns a detection alert into evidence a regulator or an auditor can actually use under Article 72 or 73. A tool that catches the attack but produces nothing usable afterward has only solved half the problem.
Sources
- The Comprehensive Guide to Prompt Injection Attacks in 2026 | Sysdig
- Prompt injection: types, real-world CVEs, and enterprise defenses
- Indirect Prompt Injection Goes Operational – Lab Space
- LLM01:2025 Prompt Injection - OWASP Gen AI Security Project
- EchoLeak: The First Real-World Zero-Click Prompt Injection Exploit in a Production LLM System
- The Promptware Kill Chain: How Prompt Injections Gradually Evolved Into a Multistep Malware Delivery Mechanism