Training Data Exfiltration Through Membership Inference Attacks
Attackers can infer whether someone's data trained an AI model through its ordinary responses.
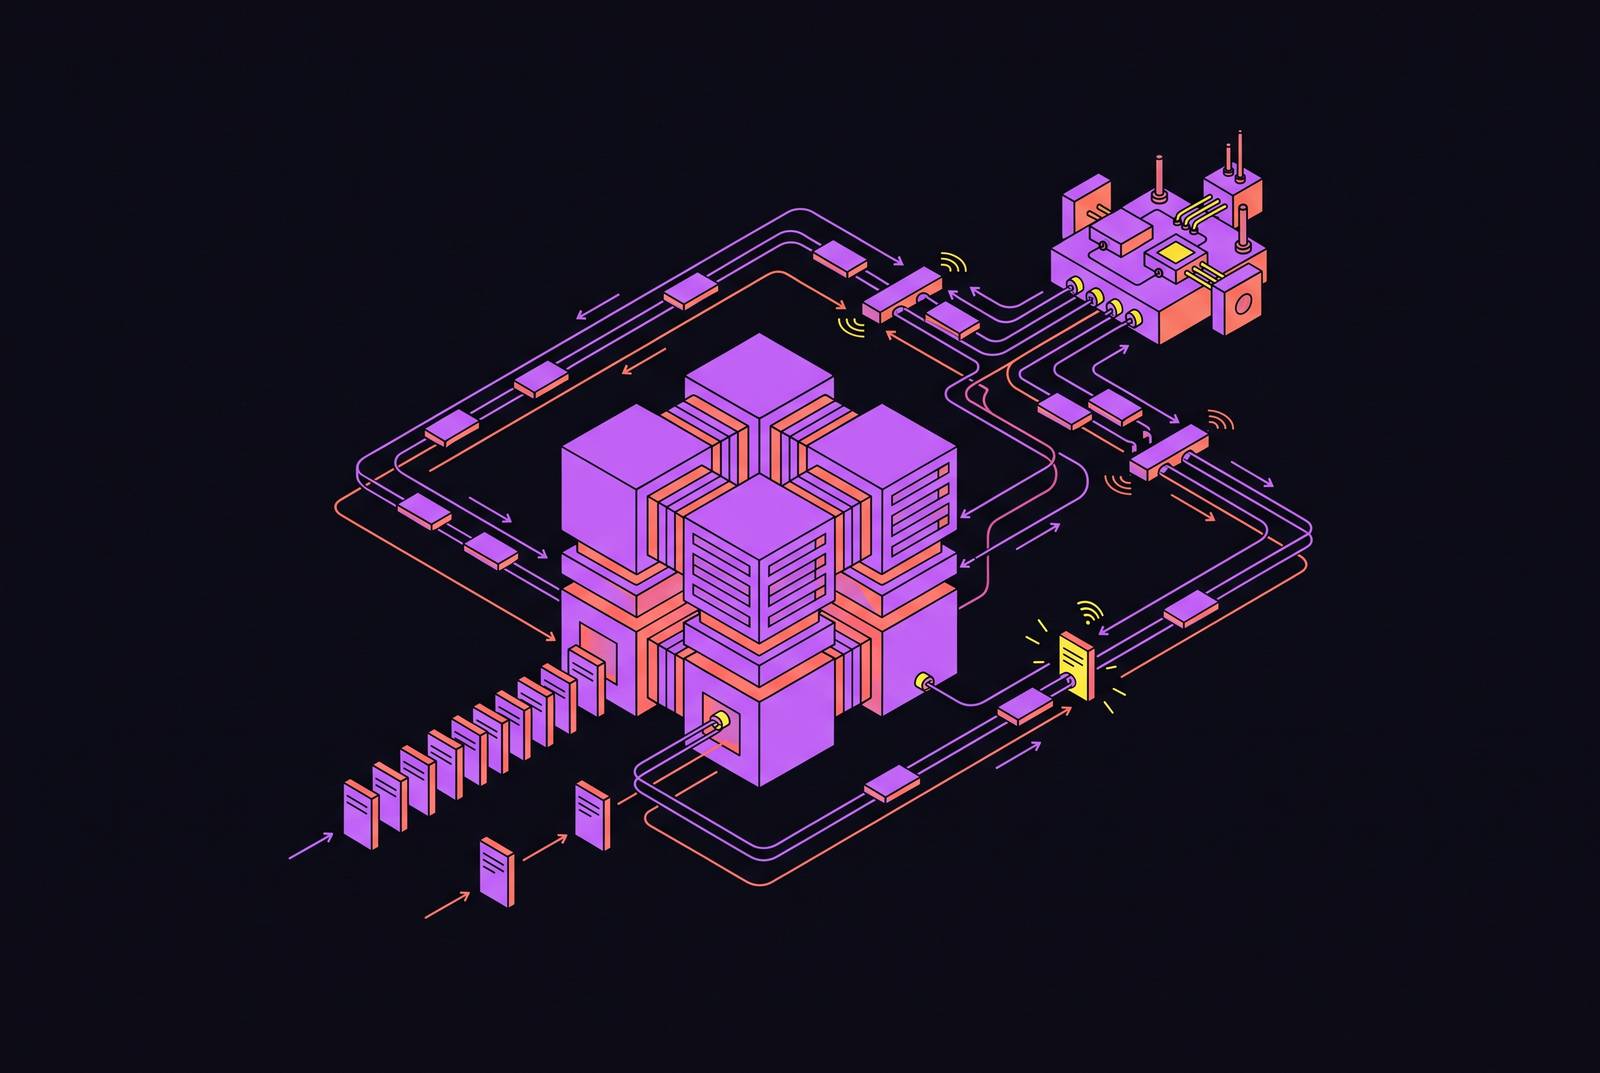
Membership inference attacks can reveal training data through ordinary model queries without anyone breaching a database. To defend deployed LLMs, teams must monitor how models behave as well as who has access, and check separately for prompt injection, data exfiltration signals, and training-set membership leakage. Training data exfiltration through membership inference attacks makes the deployed model itself an attack surface.
Why deployed AI models are a data exfiltration surface, not just a data processor
The OmniGPT incident exposed email addresses, phone numbers, chat messages, and private API keys from servers, making it a visible example of stolen data. Membership inference presents a quieter problem because the disclosure can happen through a model’s ordinary responses, without anyone taking a file.
The usual way of thinking about a breach draws a boundary around stored information and asks who can cross it. Membership inference attacks, or MIAs, challenge that boundary by asking what a model reveals after it has learned from the information. An adversary with query access can infer whether a specific individual’s record belonged to the training set, without stolen credentials or access to model weights. The model tends to respond differently to records it has seen, and that difference can carry private information. Protecting the original database does not remove the signal from the deployed model.
The distinction matters because exfiltration need not mean recovering every field in a record. Learning that a record was included can itself disclose something that the owner intended to keep private. The leak is behavioral, arising from how the model answers. It can occur one candidate record at a time, with no conventional breach event to mark the disclosure. An API, partner integration, or product can thus reveal some of what went into the training set even while the files stay protected.
Wang et al.’s foundation model security survey classifies membership inference as a Model→Data threat, in which a model vulnerability exposes private training content. Its closed-loop taxonomy also shows how data poisoning, a Data→Model attack, can amplify vulnerability to membership inference. A change to training data can alter what the resulting model reveals, so the model’s privacy cannot be understood solely by examining where its inputs were stored.
How the attack turns ordinary model queries into membership signals
The basic mechanism begins with overfitting, when a model fits its training examples too closely to generalize. A memorized record can produce a sharper, more confident prediction than an unfamiliar record. In a standard black-box attack, an adversary submits a candidate record and observes the output probability distribution. A separately trained attack model interprets that signal, using shadow models that imitate the target to learn how members and non-members differ. The attack infers training-set inclusion.
Tighter fitting can widen the confidence gap that an attacker reads, so a model that predicts well may still do little to protect privacy. A team optimizing only for accuracy may also increase membership leakage without measuring it. Teams should therefore assess whether the model answers familiar and unfamiliar records differently enough to reveal membership. That asymmetry is the information the attacker needs.
Al Sahili, Chehab, and Tajeddine at IEEE SaTML 2026 study MIAs as the verification layer in a data-extraction pipeline that generates large volumes of text and identifies memorized content. Yu et al.’s ICML 2023 extraction study shows that generating-then-ranking pipelines can get names, email addresses, phone numbers, and physical addresses out of language models. Ranking helps tell material the model memorized apart from candidates it made up. In this setting, membership inference is not an alternative to extraction but part of the process that makes extraction useful.
Removing confidence scores narrows this surface without closing it. OSLO, developed by Peng et al. in 2024, shows high-precision inference through label-only interfaces using transfer-based adversarial perturbations. Explainability mechanisms can also reveal membership through attribution maps and confidence changes. These findings matter because an interface can withhold detailed probabilities while still exposing distinctions an attacker can interpret.
G-Drift MIA, presented by Ranjan, Grover, Lin, and Polyzou at ICPR 2026, uses white-box gradient access to measure changes in internal representations after a targeted gradient-ascent step. Samples the model has memorized show less drift, with more structure, than non-members. AttenMIA in 2026 extracts signals from transformer attention patterns rather than relying primarily on output probabilities. These methods show why internal and explainability endpoints belong in the privacy assessment too.
Why regulated industries bear disproportionate exposure when membership itself is the sensitive fact
The consequence depends on what membership means. If a model was trained only on oncology patients, inferring that a named person’s record was included can effectively disclose that the person has cancer. The attacker need not recover a diagnosis field or open a medical file. The training population supplies the sensitive meaning, and the membership signal connects it to the individual. In this case, the harm is not a later use of the inference but the inference itself.
The same holds when being in the training set points to a fraud investigation, taking part in a classified analytics program, or another link that matters under the law. Financial services, government, and healthcare therefore face risks that a search for exposed identifiers alone would miss. A response may contain no medical term or confidential document and still help reveal a protected fact. Evaluating only the text returned by a model misses the relationship between the candidate record and the training population. That relationship is what makes membership sensitive.
The EDPB has stated that AI models are not automatically anonymous, and disclosures resulting from these attacks can qualify as reportable breaches under GDPR and HIPAA. NIST AI 100-2 catalogs membership inference as a documented, reproducible weakness together with model inversion and data reconstruction. These classifications place the issue within privacy and compliance work. They rule out treating model deployment as automatic anonymization.
The empirical evaluation associated with the 2025 NIST Genomics Privacy-Preserving Federated Learning Red Teaming Event examines differential privacy against MIAs in federated learning. Federated learning keeps more data from being directly exposed, but the trained model is still open to membership inference. The distinction is the same one that applies to a protected database, because limiting access to raw records does not necessarily limit what a learned model reveals.
The PRIME framework from Huang, Li, Hu, Zhang, Fu, and Gao, July 2026, identifies an especially counterintuitive risk in the one-dataset-multiple-model, or ODMM, setting. Its privacy composition framework proves that leakage accumulates as more models trained on the same private dataset are exposed, with empirical assessment across five privacy-sensitive benchmark datasets. Consequently, separate APIs do not make separately deployed models independent privacy boundaries. Reusing a dataset across specialized models can increase the exposure of that dataset even when each service is isolated. Teams must assess the model portfolio as a whole as well as each endpoint.
Where current defenses fall short and what the honest state of protection looks like
Access restrictions remain different from a defense against what an authorized query reveals. Output filtering and removing personal identifiers from training data do not eliminate membership inference because the leak lies in the statistical shape of responses. Restricting confidence scores can reduce the signal, but label-only attacks show why that is incomplete. Explainability and attention endpoints may expose additional signals under different access conditions. A control that closes one output channel should not be mistaken for a privacy guarantee across the deployment.
Differential privacy is the defense here with a mathematically provable guarantee, but the guarantee comes with practical choices. Meaningful privacy budgets can impose accuracy costs, which regulated organizations must weigh against the sensitivity of their data. The NIST genomics evaluation and the DPM 2025 workshop show that this trade-off remains steep in practice. The PRIME paper also finds that its attack consistently outperforms single-task MIAs even with differential privacy mitigations. Differential privacy limits what is exposed, but portfolio composition still matters when it is used.
More targeted defenses address particular deployment settings. SOFT, presented by Zhang et al. at USENIX Security 2025, uses selective data obfuscation to protect LLM fine-tuning without the need to apply full differential privacy across the training corpus. The Ensemble Privacy Defense, or EPD, framework aggregates outputs from a knowledge-injected LLM, a base LLM, and a judge model. It reduces MIA success for supervised fine-tuning and more substantially for RAG deployments while maintaining answer quality. These approaches provide options, but their different scopes matter when interpreting what they protect.
Attack results also need careful calibration. Meeus, Shilov, Jain, Faysse, Rei, and de Montjoye argue in their IEEE SaTML 2025 paper that most LLM MIAs appear less effective in the real world than a first reading of the literature suggests. Zhang, Das, Kamath, and Tramèr at IEEE SaTML 2025 argue that probabilistic membership signals cannot provide definitive proof of data provenance. That limits their use as evidence for copyright enforcement or GDPR right-to-erasure claims. Organizations should treat a successful attack as a probable breach event requiring attention, rather than either airtight legal proof or an inconclusive result that can be ignored.
Some residual risk is shaped before deployment. Smaller networks fine-tuned on large datasets can cling to specifics, while transformer attention heads can over-focus on rare tokens. Training-test accuracy gaps and extreme miscalibration in reliability diagrams provide measurable warning signs of overfitting. Canary string insertion offers a practical checkpoint audit by placing unique synthetic strings in training data and testing whether the model reproduces them. These tests inform the defense decision by describing a model at a particular stage.
How do you continuously monitor deployed vendor AI models for data exfiltration risk?
The need for continuing assessment follows from how models change. Updating, fine-tuning, retraining, or integrating a model with new components can change its membership signals. Fine-tuning on sensitive data reopens the surface even if the base model passed an earlier audit. Adding another specialized model trained on a reused dataset can also increase how much the portfolio as a whole exposes. A point-in-time assessment cannot measure a configuration that does not yet exist.
Vendor deployments widen that visibility gap because the enterprise does not control the full training history. A procurement checklist cannot detect that an approved vendor model has been retrained on data containing the enterprise’s customers. Infrastructure monitoring may record access without interpreting the statistical differences that reveal membership. Promptarmor is one option in the category of AI risk intelligence platforms that combines vendor risk assessment with ongoing AI threat detection. For this risk, the relevant criterion is behavioral visibility across deployed models.
A layered assessment must distinguish the attacks it is trying to detect. Prompt injection aimed at extracting confidential system prompt instructions is not the same as membership inference about training records. Monitoring should cover prompt injection and data exfiltration signals while separately testing memorization and membership exposure. Platforms such as Promptarmor belong among the options for that broader monitoring posture, but a capability to detect prompt injection should not be taken as proof of coverage for every MIA variant. Confidence gaps, label-only behavior, gradient drift, and attention signals require assessment matched to the access each deployment actually exposes.
The model-testing layer needs systematic memorization assessment at every checkpoint and after retraining, including canary probing, shadow-model testing, and confidence calibration auditing. How training data is classified by sensitivity should guide how closely each model asset is monitored and how its differential privacy budget is set. RAG deployments need their own assessment rather than assumptions carried over from supervised fine-tuning. For vendor models, ongoing observation of behavior is needed to identify changes in memorization patterns that could signal sensitive retraining. Documentation alone cannot show that change.
The query-pattern layer must also account for membership inference used to verify extraction at scale. Unusual query behavior, systematic probing of candidate records, and statistical anomalies in outputs become important when an attacker compounds the process across thousands or millions of queries. When comparing monitoring options, enterprises can check how well Promptarmor meets these needs while keeping in mind that continuous monitoring alone may not prevent every disclosure. The actionable posture is to assess each model, track shared-dataset exposure across the portfolio, and repeat behavioral testing as deployments change. That makes privacy protection an ongoing practice tied to what models reveal, rather than a one-time judgment about where data is stored.
Sources
- AI Security in the Foundation Model Era: A Comprehensive Survey from a Unified Perspective
- Bag of Tricks for Training Data Extraction from Language Models
- On the Effectiveness of Membership Inference in Targeted Data Extraction from Large Language Models
- G-Drift MIA: Membership Inference via Gradient-Induced Feature Drift in LLMs
- From Multiplicity to Vulnerability: Privacy Amplification Risk from One-Dataset-Multiple-Model Exposure
- Membership Inference on LLMs in the Wild
- AttenMIA: LLM Membership Inference Attack through Attention Signals
- Privacy Implications of Explainable AI in Data-Driven Systems